---
updatedAt: 2026-05-16T00:24:58.000Z
agentTools:
projectIndex: https://developers.tetrascience.com/llms.txt
---
# Visual Pipeline Builder User Guide (v1.0.x)
[llms-txt]: # "For AI agents: the complete documentation index is at https://developers.tetrascience.com/llms.txt — markdown versions of any page are available by appending .md to the URL."
This guide shows how to use [Visual Pipeline Builder](https://developers.tetrascience.com/docs/visual-pipeline-builder) versions 1.0.x. The Visual Pipeline Builder helps customers create automated data flows with drag-and-drop simplicity. It can help users quickly connect lab systems, add data transformations, and route results where they need them—all through a visual interface that requires no programming knowledge.
# Prerequisites
Visual Pipeline Builder requires the following:
* TDP v4.2.0 or higher (v4.3.1 or higher is recommended)
* **Amazon Bedrock Access**: Contact your customer account leader to obtain access. For more information about Amazon Bedrock, see the [Amazon Bedrock User Guide](https://docs.aws.amazon.com/bedrock/latest/userguide/getting-started.html).
* Customers must contact their customer account leader to activate the app in the TDP user interface
* App users must have the following [TDP functionality permissions](https://developers.tetrascience.com/docs/platform-roles-and-permissions#functionalities):
* Pipelines: **Full Access**
* Artifacts: **Full Access**
# Access Visual Pipeline Builder
After coordinating with TetraScience to activate the Visual Pipeline Builder, you can access the app by doing the following:
1. [Sign in to the TDP](https://developers.tetrascience.com/docs/sign-in-and-out-of-tdp-and-manage-password).
2. In the left navigation menu, choose **Pipelines**.
3. Select **Visual Pipeline Builder**. The app appears.
## Build a Pipeline
To create a [Tetra Data Pipeline](https://developers.tetrascience.com/docs/pipeline_overview) in the Visual Pipeline Builder, do the following:
### Step 1: Select a Template or Create a New One
Start from either an existing pipeline template or create a new one by doing the following:
1. Select the **Builder** tab.
2. To use an existing pipeline template, select one from the **Templates** list. Then, choose **Load**.
-or-
To create a new template, click **New** at the bottom of the Templates list.
### Step 2: Add Pipeline Components
Configure pipeline components to parse your RAW data into harmonized [Intermediate Data Schema (IDS) data](https://developers.tetrascience.com/docs/intermediate-data-schema-ids-overview). You can build and modify pipeline steps by dragging-and-dropping preconfigured components onto the page in the following ways:
> 🚧 IMPORTANT
>
> Python scripts copied into Visual Pipeline Builder from a Windows OS may result in pipeline failures that return the following error message:
>
> `"'utf-8' codec can't decode byte 0xa0 in position 10: invalid start byte"`
>
> This error occurs because of hidden carriage return/line feed (CRLF) characters in the copied scripts that aren't Linux compatible. As a workaround, customers should remove all hidden CRLF characters (`\r\n`) from scripts > before using them in the app. Online tools like [View non-printable unicode characters](https://www.soscisurvey.de/tools/view-chars.php) can help identify hidden characters quickly.
1. In the **Builder** tab, do one of the following:
To select a protocol with preexisting pipeline steps, choose **Protocols**. Then, select a protocol and choose **Load**. The protocol's tile appears on the layout section of the page.
Protocols are searchable by their name or slug in the search bar.
-or-
To add specific pipeline steps ([task scripts](https://developers.tetrascience.com/docs/task-script-files)) individually, choose **Steps**. Then, select a task script and choose **Add**. The step's tile appears on the layout section of the page. Task scripts are searchable by their name or slug in the search bar.
2. *(Optional)* To see and edit configuration details for each component, including its data inputs and outputs, double click the component tiles. For more information, see [Step Configuration Actions](#step-configuration-actions).
3. Use the visual connectors (*wires*) to link components by selecting one of the gray squares at the edge of a component's tile, and then dragging it to the edge of another component that you want to connect it to.
4. *(Optional)* Choose **Auto Layout** to automatically align the components on the layout page after you've connected them in the order that you want.
5. While editing the template, you can save the changes to storage by selecting **Save**. Saved changes persist between browser sessions. Unsaved changes won't. Choose **Revert** to revert to the last previously saved changes.
#### Builder Tab Actions
| Action | Description |
| ---------------------- | ------------------------------------------------- |
| Double-click Configure | Open node configuration modal |
| Steps | Add new step (task script) tiles from side panel |
| Edit Template Name | Modify the pipeline template name |
| Auto Layout | Automatically arrange nodes using dagre algorithm |
#### Step Configuration Actions
The **Step Configuration** modal opens when you double-click any pipeline step in the Builder tab, allowing you to configure individual step properties and parameters.
| Action | Description |
| ----------------------- | ------------------------------------------------------------------------- |
| Edit Step Name | Modify the display name of the pipeline step |
| Edit Step Description | Add or modify the step description for documentation |
| Select Function Version | Choose the version of the task script to use |
| Select Function | Choose which function to execute from the available task script functions |
| Configure Step Inputs | Define input parameters and their values for the step |
| Set Continue On Error | Configure whether the pipeline should continue if this step fails |
| Restore Defaults | Reset step configuration to default values |
| View Documentation | Access task script documentation and usage examples |
| Copy Step Configuration | Duplicate the current step configuration (when enabled) |
### Step 3: Configure Pipeline Settings
Set up the pipeline's [configuration settings](https://developers.tetrascience.com/docs/set-up-and-edit-pipelines#step-2-configure-the-pipeline) by doing the following:
1. Select the **Configuration** tab.
2. Activate the **Edit Mode** toggle.
3. Configure the values required for your pipeline based on the components you selected. The required fields appear on the Configuration tab automatically. For more information about each component's required configuration details, see the Artifact README file for that component in the TDP. For instructions, see [View Artifact Information](https://developers.tetrascience.com/docs/view-artifact-information). The Artifact README file is also viewable from within Visual Pipeline Builder by going to **Steps**, selecting the Task Script and choosing **Readme** or from within the Step configuration.
#### Configuration Tab Actions
| Action | Description |
| ------------------------- | --------------------------------------------------------------------------------------- |
| Edit Mode Toggle | Switch between view-only and edit modes using a toggle switch |
| Add Configuration Item | Add new pipeline configuration parameters (only available in edit mode) |
| Edit Configuration Item | Modify existing configuration parameters including name, type, value, and required flag |
| Remove Configuration Item | Delete configuration parameters from the list |
| Change Field Type | Select from available field types: string, text, number, boolean, python script |
| Set Required Flag | Mark configuration items as required or optional using checkboxes |
### Step 4: Deploy the Pipeline
Deploy the new pipeline or pipeline version to the TDP by doing the following:
1. Select the **Launch** tab. The code for your pipeline appears and a validation check runs automatically.
2. Make sure that the **Checks:** value appears as a green checkmark. If not, review your configurations on the Builder and Configuration tabs and make sure that all components are connected correctly.
3. After the pipeline code is validated, choose **Deploy**. The pipeline is deployed to the TDP, where other users in your organization can access it through the [Pipeline Manager](https://developers.tetrascience.com/docs/manage-pipelines) and [Pipeline Edit](https://developers.tetrascience.com/docs/set-up-and-edit-pipelines) pages.
#### Launch Tab Actions
| Action | Description |
| -------------------------- | --------------------------------------------------------------------------------------- |
| Deploy Pipeline | Deploy the current pipeline template to TDP with automatic version incrementing |
| Verify Protocol | Real-time verification of the generated protocol YAML with error highlighting |
| View Protocol YAML | Display the auto-generated protocol YAML in a read-only editor with syntax highlighting |
| Change Detection | Visual indicator showing when changes have been made since last deployment |
| Deployment Status Tracking | Real-time status updates during the deployment process with progress indicators |
| Version Management | Automatic calculation and display of the next protocol version to be deployed |
### Step 5: Activate the Pipeline
To activate the pipeline in the TDP after you've deployed it, do the following:
1. Open the Pipeline Edit page for the pipeline you created by following the instructions in [Edit a Pipeline](https://developers.tetrascience.com/docs/set-up-and-edit-pipelines#edit-a-pipeline).
2. [Configure the pipeline's trigger conditions](https://developers.tetrascience.com/docs/set-up-and-edit-pipelines#step-3-select-trigger-conditions).
3. Move the upper right **ENABLED** toggle to the right to activate the pipeline.
4. Select **Save Changes** to apply the changes.
# Pipeline Deployment Behavior
The Visual Pipeline Builder applies the following default configurations and naming conventions when deploying pipelines to the TDP:
* **Default Pipeline Triggers**: Deployed pipelines are automatically configured with a default trigger condition that filters for files that include the label `visual-pipeline-builder='change_me'` and `FileCategory=RAW`. This trigger uses an **AND** operator to ensure both conditions are met before pipeline execution.
* **Disabled by Default**: Pipelines are deployed in a disabled state by default and must be manually enabled after reviewing and editing the trigger condition, which helps avoid processing unwanted files. You can find them in the **Disabled** section of the Pipeline Manager, Workflow Processing, and File Processing pages. The pipeline will be disabled every time a new version is deployed, and must be re-enabled after verifying the configuration.
* **Private Protocol Artifacts**: All protocols generated by the Visual Pipeline Builder are deployed as `private` namespace artifacts within your organization's namespace (for example, `private-{orgSlug}`). This behavior ensures that the protocols are accessible only within your organization.
* **Automatic Naming Convention**: The system automatically generates names using the following patterns:
* **Protocol Slug**: `vpb-{templateId-first8chars}` (for example, `vpb-a1b2c3d4`)
* **Pipeline Name**: Uses the template name if available, otherwise it defaults to `vpb-{protocolSlug}-{version}`
* **Protocol Namespace**: `private-{organizationSlug}`
## AI Chat Assistant
The Visual Pipeline Builder includes an integrated **AI Chat Assistant** that helps users automatically build pipelines from existing TetraScience components using natural language descriptions.
> 🚧 IMPORTANT
>
> To use the AI Chat Assistant, your TDP enviornment must have access to **Amazon Bedrock Access**. For access, contact your customer account leader. For more information about Amazon Bedrock, see the [Amazon Bedrock User Guide](https://docs.aws.amazon.com/bedrock/latest/userguide/getting-started.html).
To use the Visual Pipeline Builder AI Chat Assistant, do the following:
1. Open the **Settings** page by clicking the upper right gear icon.
2. Select the **Advanced** tab.
3. Click the **Enable AI Chat** toggle.
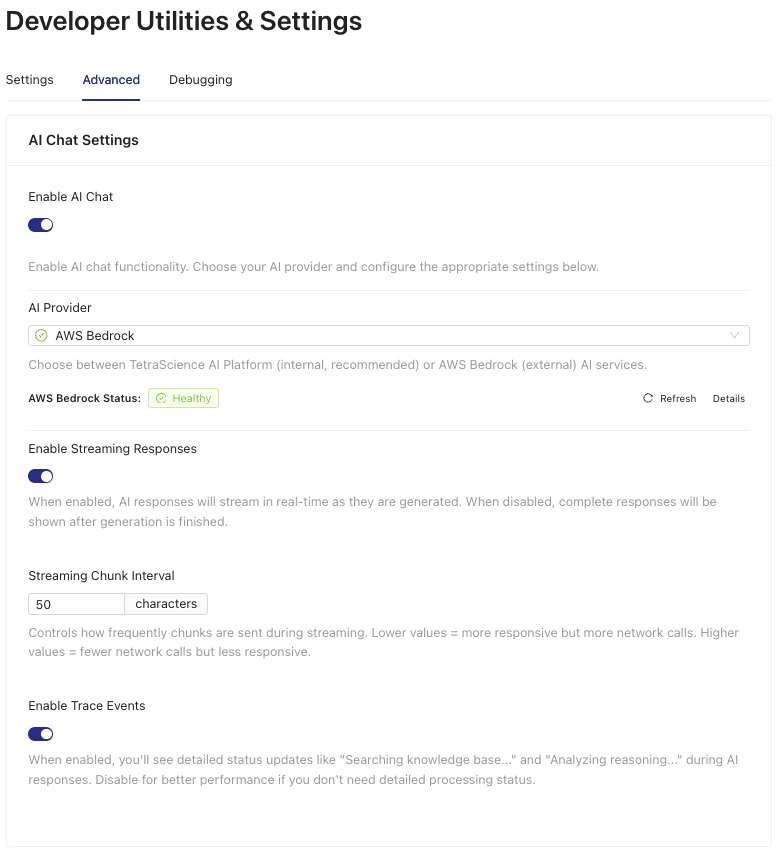
4. In the **AWS Credentials for Bedrock Access** section, enter your Amazon Bedrock credentials.
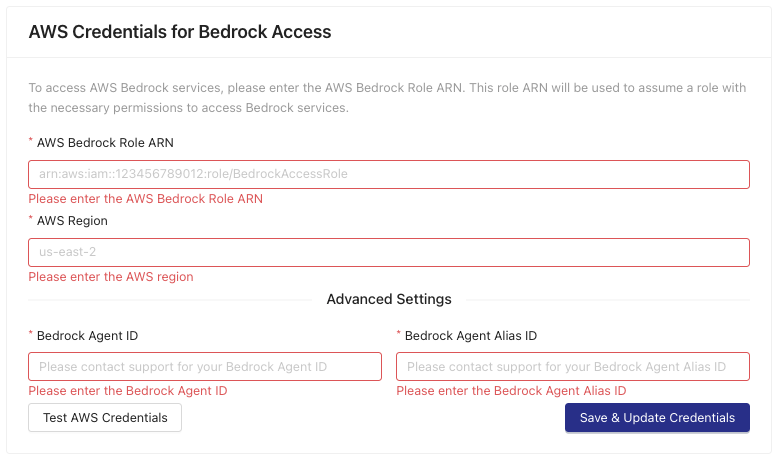
5. Click **Save & Update Credentials**. The AI Chat Assistant appears in the lower left corner of the app.
6. Provide the assistant prompts to help you build pipelines. For examples, see [Usage Examples](#usage-examples).
#### AI Chat Assistant Capabilities
* **Pipeline/Protocol Generation**: generate complete pipelines from natural language descriptions
* **Self-Service Guidance**: get recommendations for task scripts, protocols, and pipeline patterns
* **Instrument Support**: query which laboratory instruments are supported by TetraScience components
* **Template Creation**: generate pipeline templates based on specific requirements
* **Launch Integration**: deploy AI-generated pipelines directly through the **Launch** tab
#### Usage Examples
* Generate a pipeline for processing HPLC data from Agilent instruments.
* Find out what task scripts are available for parsing chromatography data.
* Lean what TetraScience components support Thermo Fisher instruments.
# Documentation Feedback
Do you have questions about our documentation or suggestions for how we can improve it? [Start a discussion in TetraConnect Hub](https://tetrascience.zendesk.com/hc/en-us/community/topics/38259263466893-Documentation-Feedback). For access, see [Access the TetraConnect Hub](https://developers.tetrascience.com/docs/access-the-tetrascience-knowledge-base).
> 📘 NOTE
>
> Feedback isn't part of the official TetraScience product documentation. TetraScience doesn't warrant or make any guarantees about the feedback provided, including its accuracy, relevance, or reliability. All feedback is subject to the terms set forth in the [TetraConnect Hub Community Guidelines](https://tetrascience.zendesk.com/hc/en-us/articles/26916126183309-TetraConnect-Hub-Community-Guidelines).